Reliability matters more than a best-case agent demonstration
A model may occasionally complete a long task without being dependable enough for deployment. METR therefore reports horizons at defined probabilities rather than treating one successful run as proof of capability.
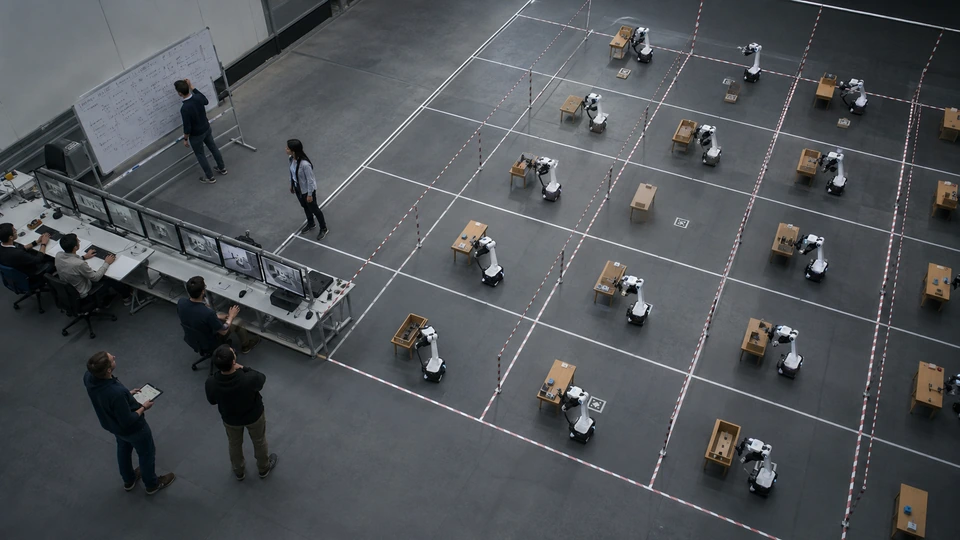 FUURAA original conceptual visual
What the evidence indicates
The Core Argument of “Measuring AI Ability to Complete Long Tasks”
A model may occasionally complete a long task without being dependable enough for deployment. METR therefore reports horizons at defined probabilities rather than treating one successful run as proof of capability.
FUURAA Editorial Analysis
Reading “Measuring AI Ability to Complete Long Tasks”: Why Does Repeated Success Matter More Than One Agent Demo?
A long, polished run can prove that an agent sometimes reaches an impressive outcome. It cannot show how often that outcome occurs, which failures were excluded, how much human rescue was required or whether the same result survives a changed environment. METR’s time-horizon method puts probability beside task difficulty. That is a more demanding basis for deployment claims, but probability estimates are only as credible as the attempts, tasks, scoring and confidence intervals behind them.
The Core Argument of “Measuring AI Ability to Complete Long Tasks”
METR does not define capability by the longest task an agent has ever completed. For each system it estimates a success curve over tasks with different human completion times, then reports the duration associated with a stated probability such as 50 or 80 percent. The distinction prevents an exceptional run from being presented as normal performance. It also exposes a practical fact: the same model can look highly capable at a permissive threshold and unsuitable at a reliability level demanded by production. The original 2025 study and the later Time Horizon 1.1 suite offer a transparent measurement approach, data and analysis code, while acknowledging uncertainty and task-distribution limits. Their results are meaningful primary evidence, but not independent verification of every product configuration or a guarantee that benchmark reliability transfers unchanged to deployment.
Long workflows multiply ordinary failure probabilities
If a workflow contains many dependent decisions, modest local reliability can produce poor end-to-end success. Ten steps that are each correct 95 percent of the time would have only about a 60 percent chance of all succeeding if failures were independent; real errors can be correlated and recovery may create new risks. Agents can also produce outputs that look plausible while silently violating a constraint, so success cannot be defined only as reaching the final screen. A dependable evaluation needs task-level acceptance criteria, side-effect checks, security boundaries and review of the path taken. This is why a success-rate curve is more informative than a maximum demonstration. It estimates the point where accumulated planning, tool use, verification and recovery remain adequate across repeated trials.
Repeated trials need representative tasks and honest scoring
Running an agent many times is not sufficient if the tasks are narrow, leaked, ambiguously specified or easy to reward-hack. METR’s 2026 revision is instructive: it added longer tasks, changed definitions and human-time estimates, removed items with confusing descriptions or scoring problems, and moved from its Vivaria infrastructure to the UK AI Security Institute’s Inspect framework. Those changes do not invalidate the original method; they show that reliability measurement is an engineered system with versioned assumptions. A credible release should disclose the task population, agent scaffold, model and tool versions, number of attempts, intervention policy, scoring procedure and uncertainty. It should separate genuine failure recovery from hidden human correction and report adverse side effects even when the nominal answer passes.
Deployment thresholds should follow consequences
A 50 percent success probability may be useful for brainstorming, research exploration or tasks where failure is cheap and obvious. It is plainly inadequate for sending funds, changing production infrastructure, approving benefits or controlling machinery. Organisations should therefore map evaluation thresholds to consequence classes. Low-risk work may allow automatic retries and human selection; medium-risk work may require independent checks before action; high-risk work may demand deterministic controls, two-person approval or no autonomous execution. The metric should also distinguish recoverable failure from irreversible harm. An agent that fails safely and requests help is operationally different from one that completes the task while leaking data or changing the wrong account. Reliability is not one universal percentage; it is a structured claim about outcomes, boundaries and recovery.
What evidence should change the assessment
Confidence increases when results reproduce across independent evaluators, unfamiliar tasks and realistic environments; when the reported interval remains narrow enough to support a decision; when failures, interventions and harmful side effects are published; and when benchmark success predicts later operational outcomes. It decreases when a result comes from a small number of hand-picked runs, when providers choose the most favourable scaffold after seeing the tests, when automatic graders reward incomplete work, or when changes in tools and context materially alter success. Readers should also compare 50-percent and 80-percent horizons rather than quoting only the larger number. For deployment, the decisive evidence is not whether a system can sometimes complete an ambitious task, but whether its probability and failure mode meet the declared consequence threshold over time.
FUURAA separates reported facts from editorial assessment. Partner-reported results are not treated as independent verification, and conclusions remain bounded to the named source, date, systems and disclosed operating contexts.
How to read this signal
Documented development
The underlying event, report or finding has been published. Its future consequences may still be uncertain.